Basic Component
Begin Component
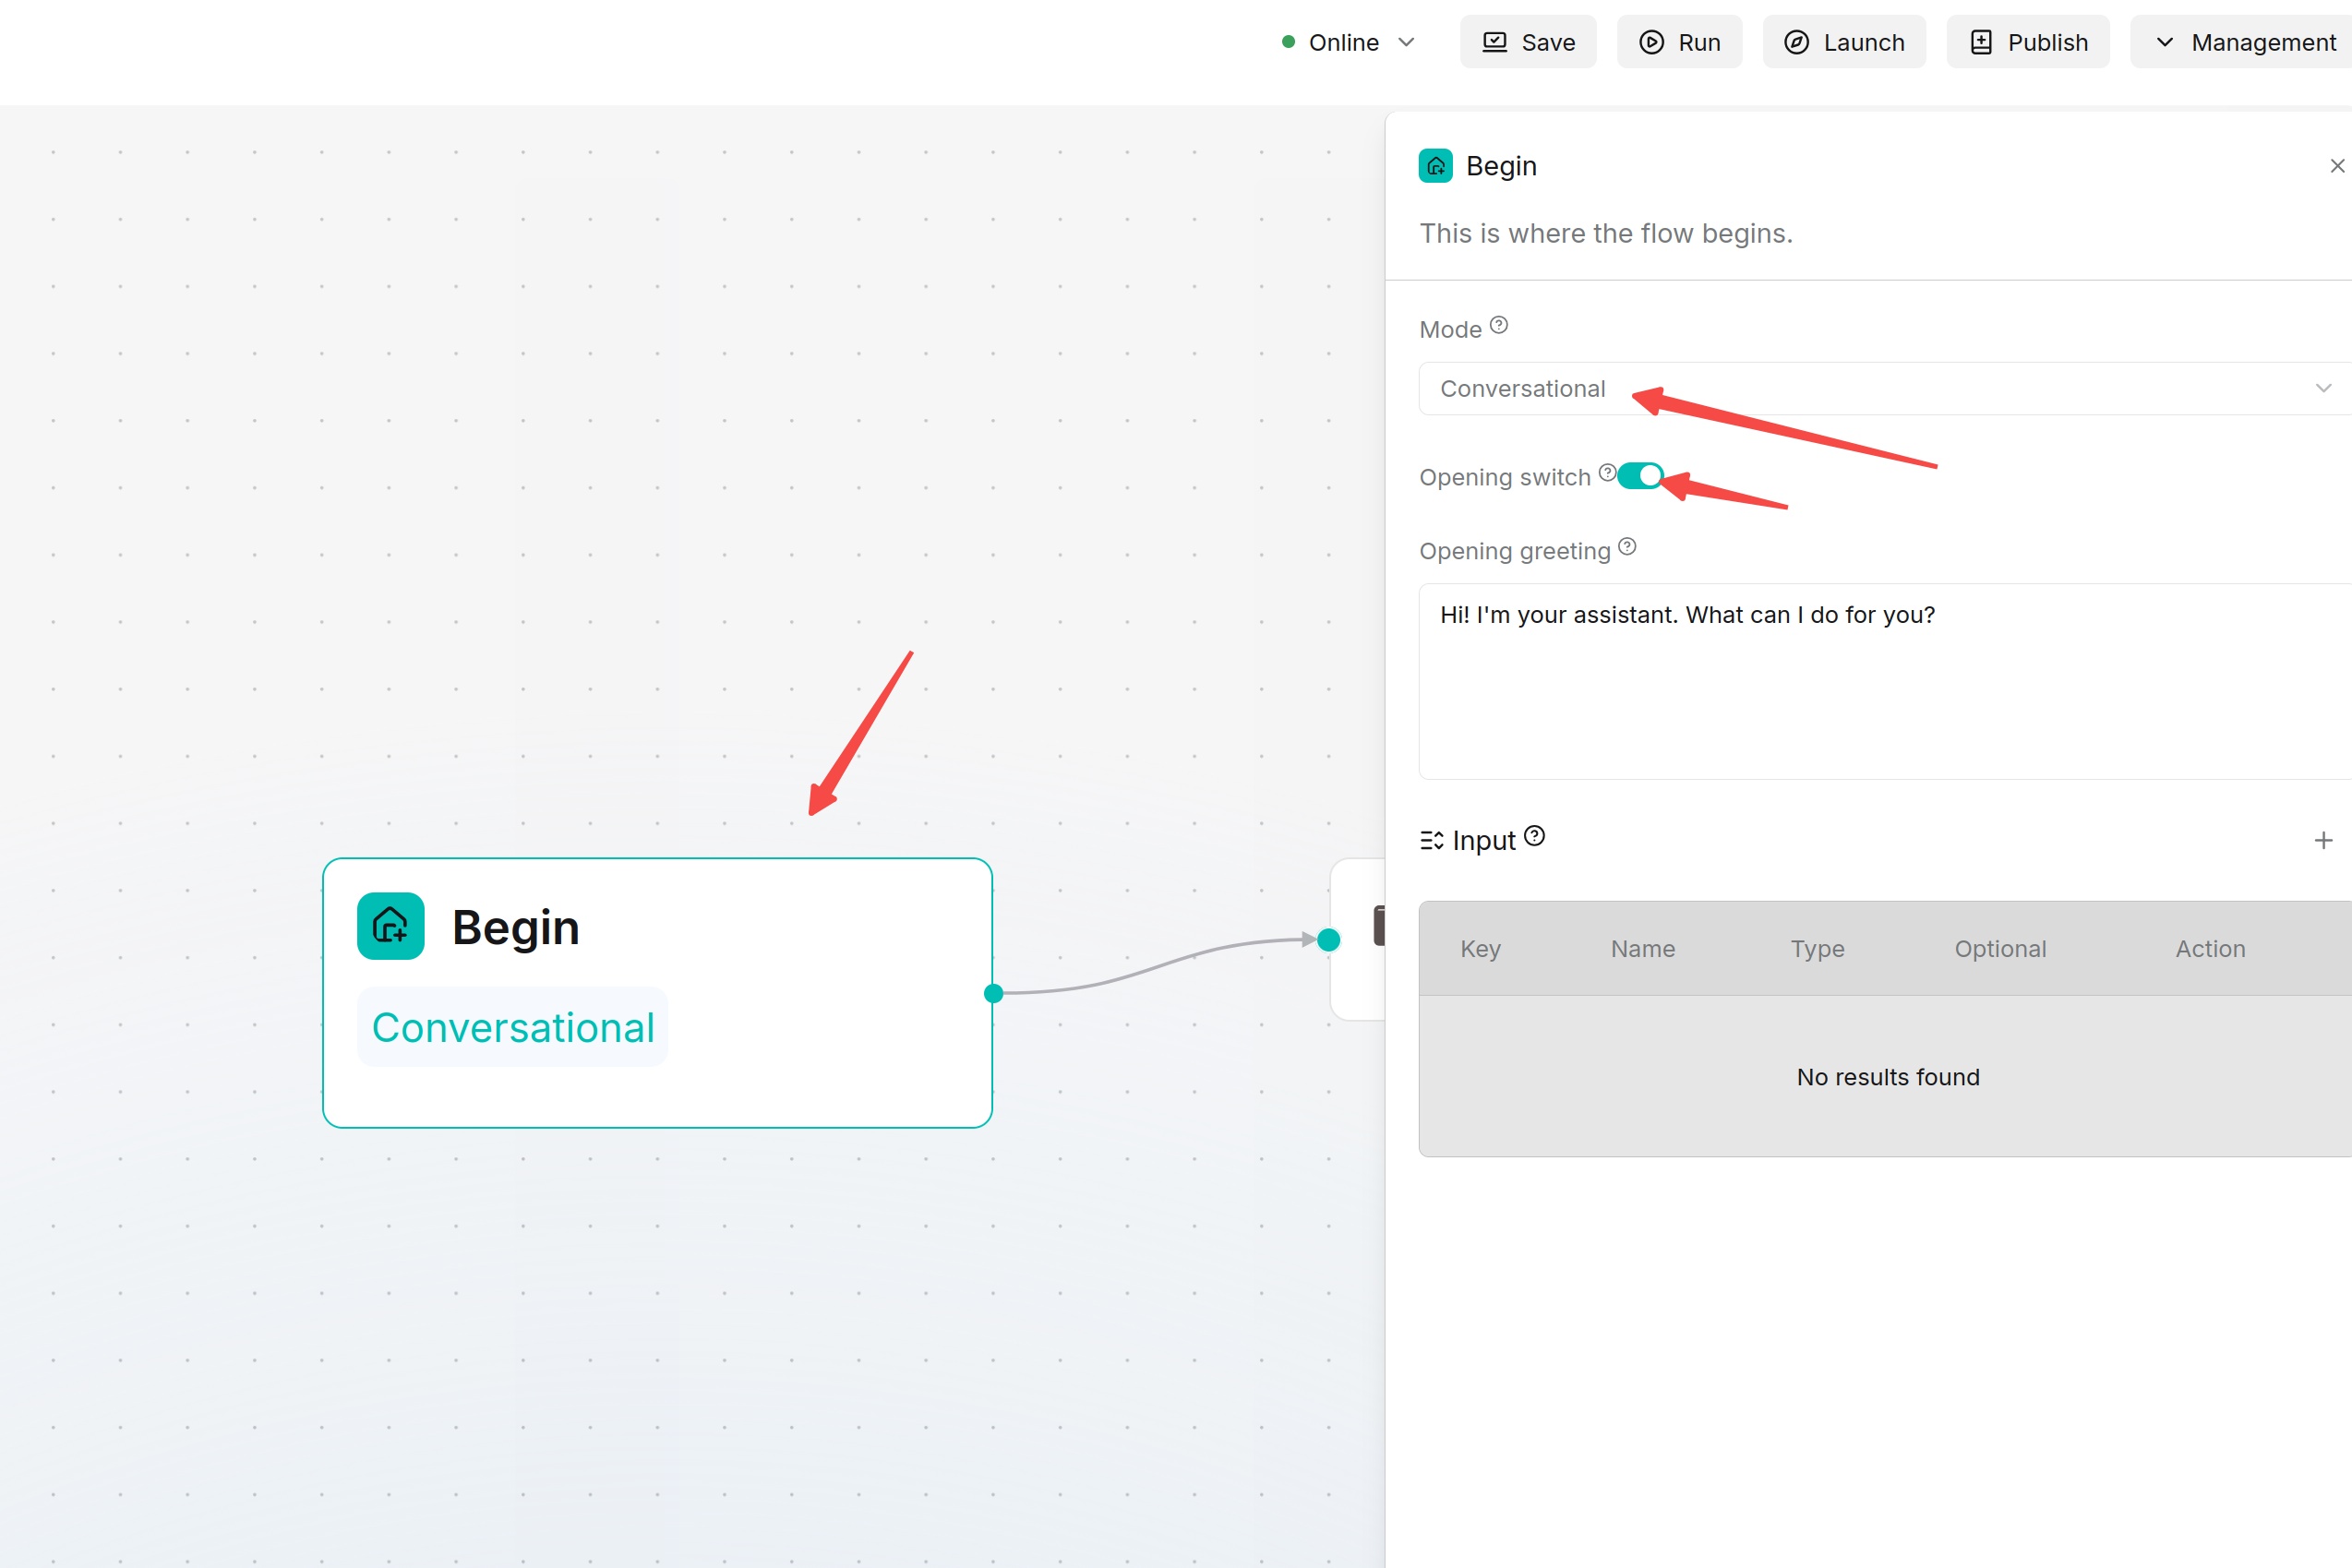
Begin is the starting point of an Agent workflow. It is used to set the trigger mode, opening greeting, and global input variables. Every Agent must contain a Begin component.
Trigger Mode
Begin supports the following modes:
- Conversational: Triggered from a conversation. This is suitable for regular chat-style Agents.
- Task: Started as a task. This is suitable for non-conversational automated workflows.
- Webhook: Triggered by external HTTP requests. This is suitable for system integration, automation tasks, and third-party callbacks.
For external HTTP requests, select Webhook and follow the Webhook configuration below.
Webhook Configuration
- In Begin, select Webhook, copy the URL, and choose the allowed request methods.
- Under Security, select the authentication method and enter its credentials. For Token authentication, set Token header to
X-Webhook-Tokenand enter Token value; the caller must send the same header and value. External requests also needAuthorization: Bearer <RAGFlow API key>from an account with access to the Agent. - Under Schema, select application/json and define the required request fields. Insert these fields into downstream components through the variable selector. Multipart file uploads are not supported and return HTTP
501. - Under Response, choose Accepted response to acknowledge the request and continue in the background, or Final response to return the completed workflow's messages. Save and test.
For example, add a required string body field named question, connect Begin → Message, and insert that field into Message. Send {"question":"Hello"} with the configured authentication and Content-Type: application/json. With Final response, the result should contain Hello.
Opening Greeting
In Conversational mode, enable Opening switch and enter an Opening greeting that briefly describes the questions or tasks the Agent can handle.
Example:
Hello, I can help you query product materials, compare models, and generate installation suggestions. Please describe your question, or upload the files that need to be analyzed.
Input Variables
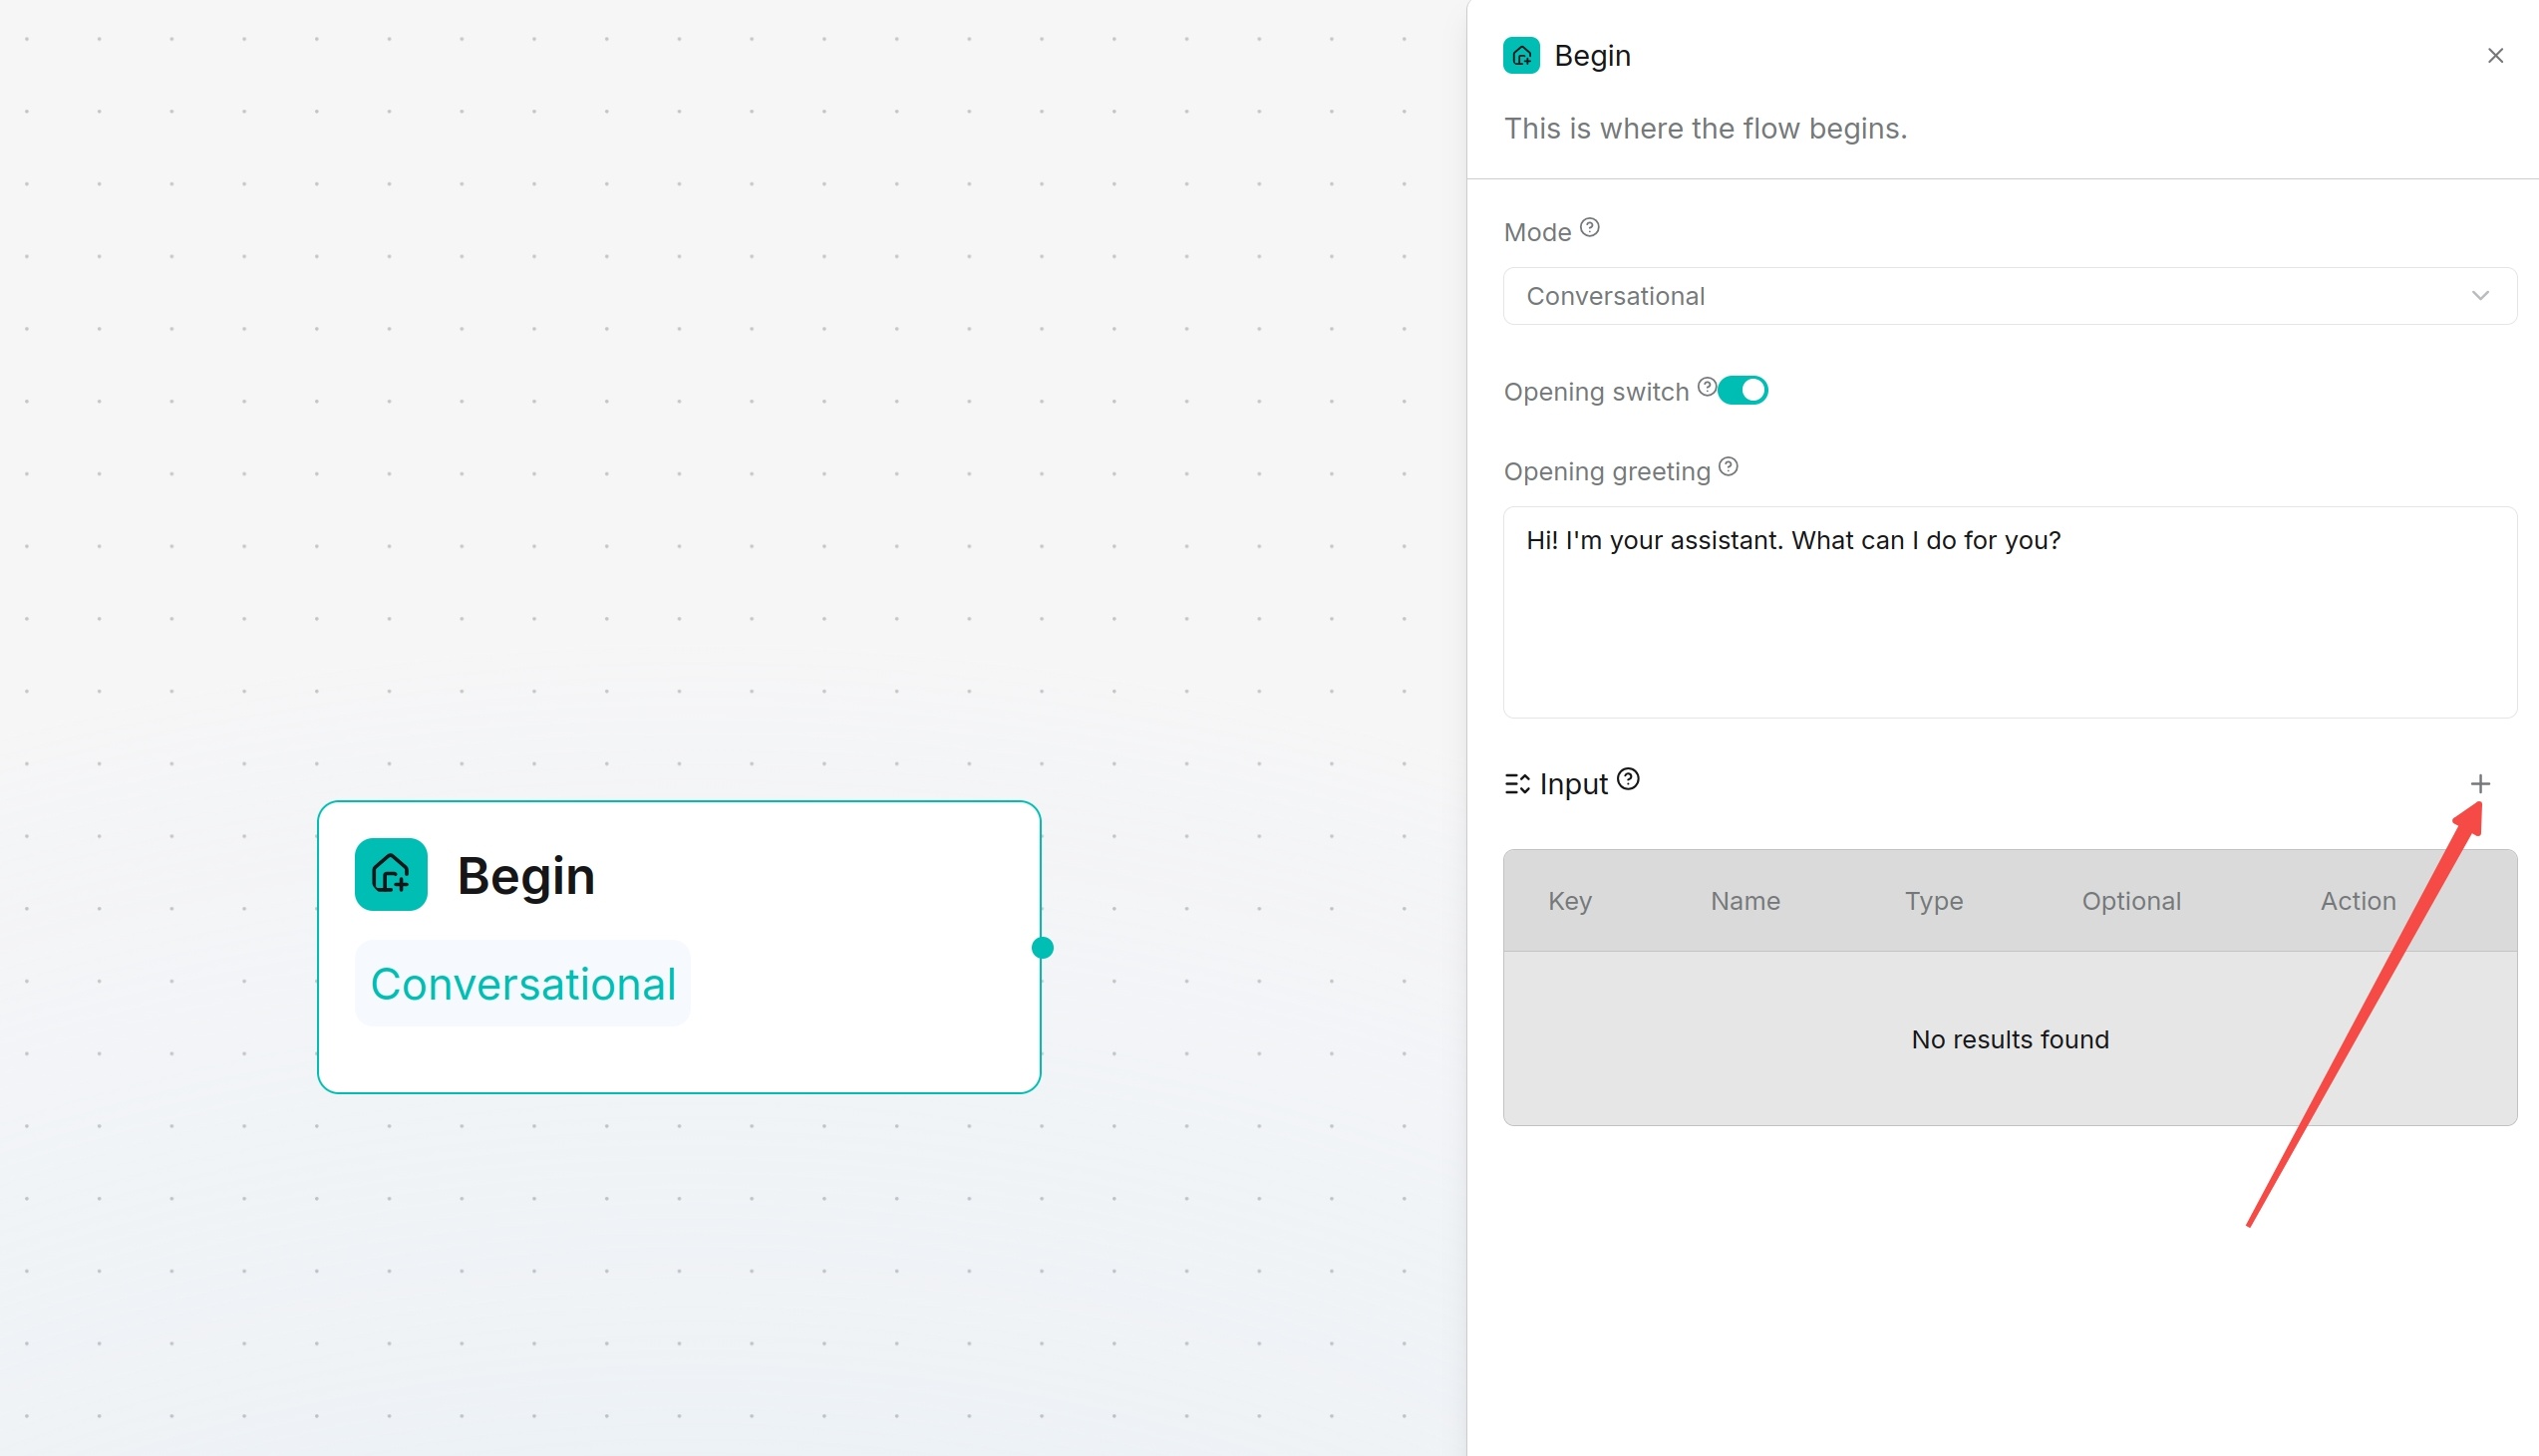
Input is used to define the input parameters that users need to provide before starting a conversation. After configuration, subsequent components can reference these inputs through variables.
In the Input area of the right configuration panel for the Begin component, click the + button in the upper right corner to add an input variable.
Common fields are as follows:
- Name: The variable display name.
- Type: The variable type, including single-line text, paragraph text, dropdown options, file upload, number, Boolean, and JSON object.
- Key: The variable key, used by subsequent components for reference.
- Optional: Whether the input is optional.
Variable types:
| Type | Description |
|---|---|
| Single-line text | Used to enter short text, such as names, keywords, and serial numbers. |
| Paragraph text | Used to enter longer content, such as problem descriptions, requirement descriptions, and prompts. |
| Dropdown options | Provides predefined options for users to select. You can click Add option to add multiple options. This is suitable for fixed-value inputs such as language, department, and model type. |
| File upload | Allows users to upload files as workflow input. This can be used for document analysis, image processing, and similar scenarios. Uploaded files are not automatically saved to knowledge bases, and are used only in the current workflow. |
| Number | Used to enter numeric values, such as quantity, threshold, Top K, and maximum returned items. |
| Boolean | Provides a switch (True/False) or yes/no option, used to control whether a feature is enabled or whether a branch is executed. |
| JSON object | Used to enter structured JSON data, such as parameters, configurations, or other complex data containing multiple fields. |
Files uploaded through Begin are available to the workflow without being added to a knowledge base.
- For documents, add a File upload input and select a parser. Reference the parsed content through
sys.filesin subsequent components. - For images, select a vision-capable model in the Agent component to analyze the uploaded image. Image uploads are not automatically converted to text.
- Video uploads are not supported in Begin.
Keep uploaded content within the selected model's context limit.
Agent Component
The Agent component is used to call large language models for reasoning, content generation, task planning, and tool calling. It can process user questions independently, or work with components such as knowledge retrieval, HTTP requests, code, databases, and sub-agents to complete multi-step tasks.
The Agent component can work independently and has the following capabilities:
- Reason, reflect, and adjust based on context and execution results.
- Call tools or sub-agents to complete tasks.
- Control reply style, task boundaries, and output format through system prompts and user prompts.
Basic Configuration
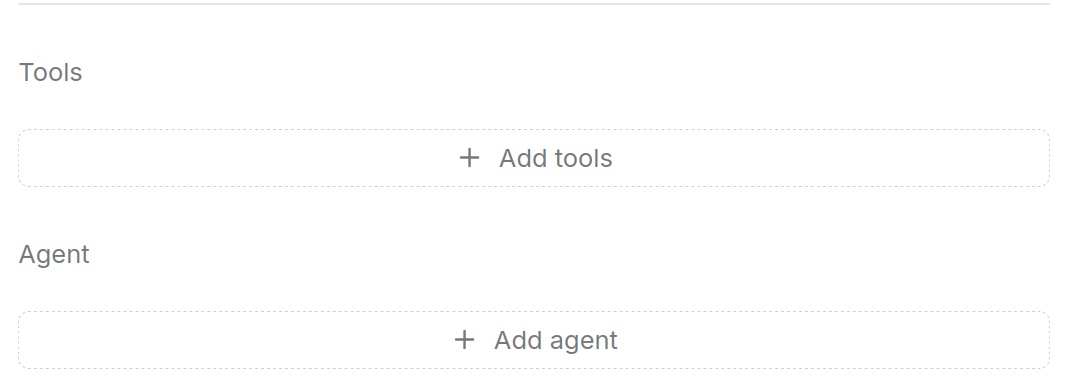
Common configuration items for the Agent component include Model, System prompt, User prompt, Tools, Agent, Message window size, Max retries, Delay after error, Max reflection rounds, and Output.
Configuration steps:
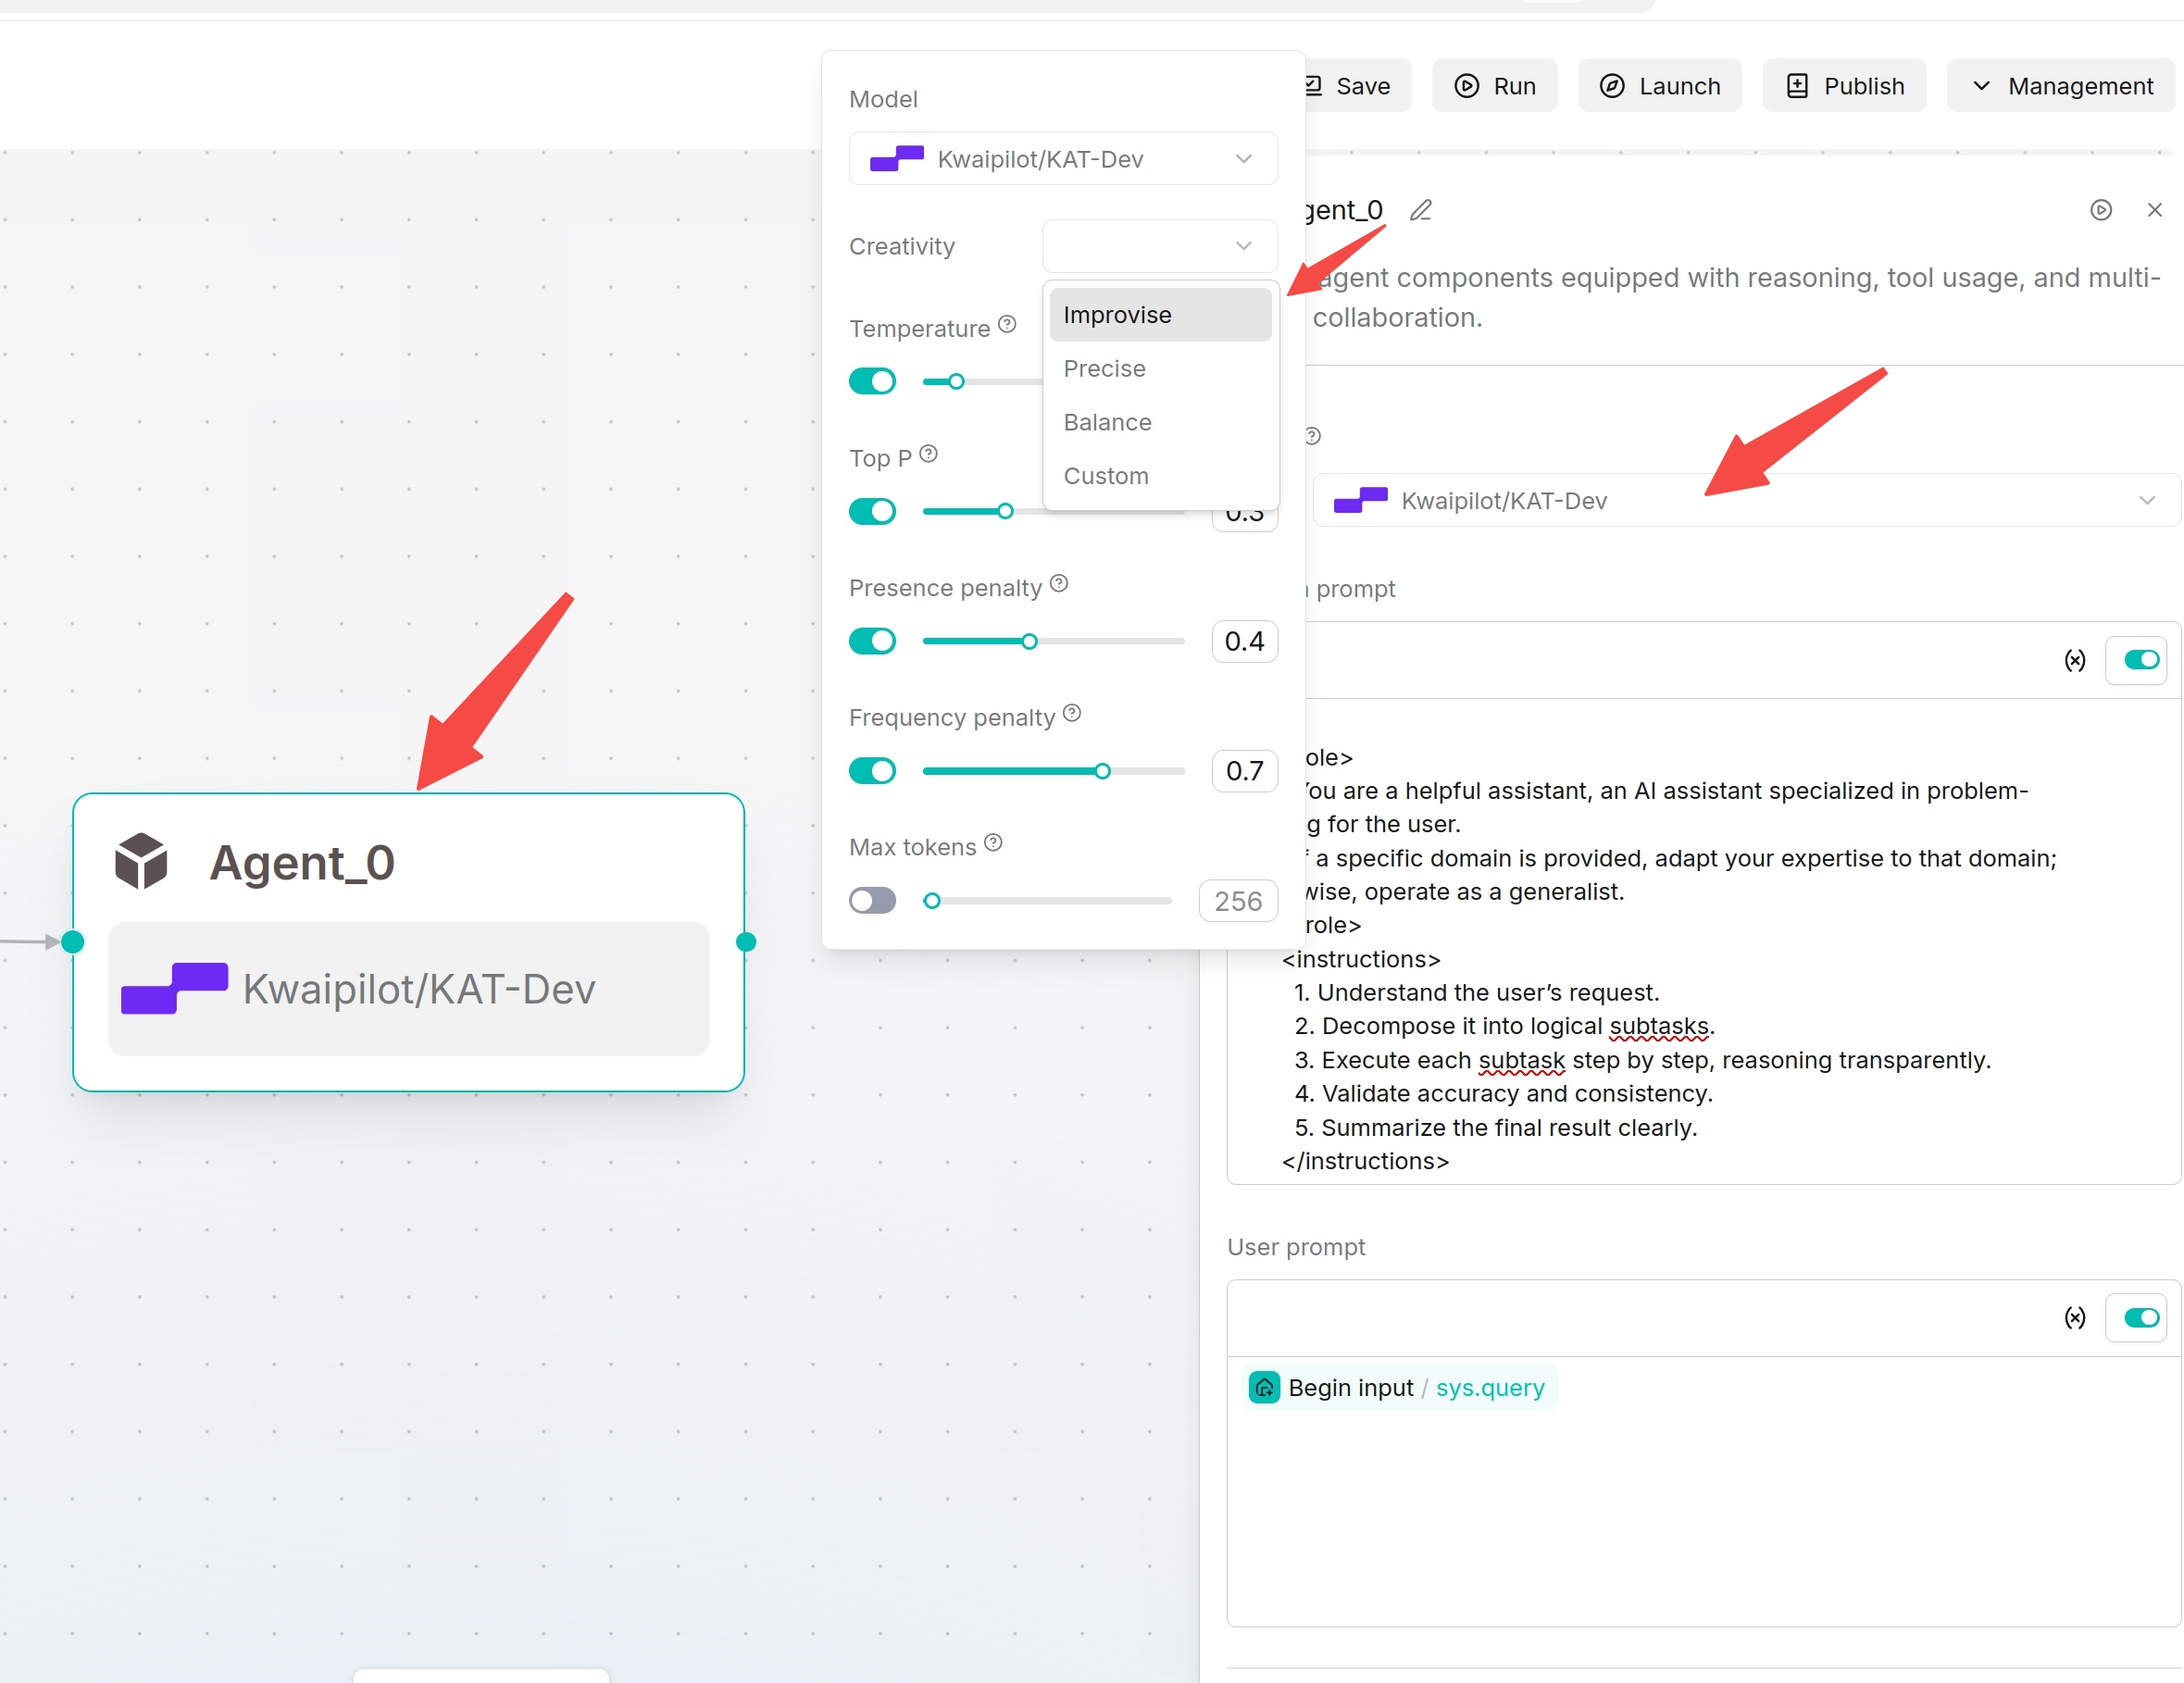
- Click the Agent component to open the right configuration panel.
- Select a chat model in Model.
- Set Creativity as needed, or keep Precise.
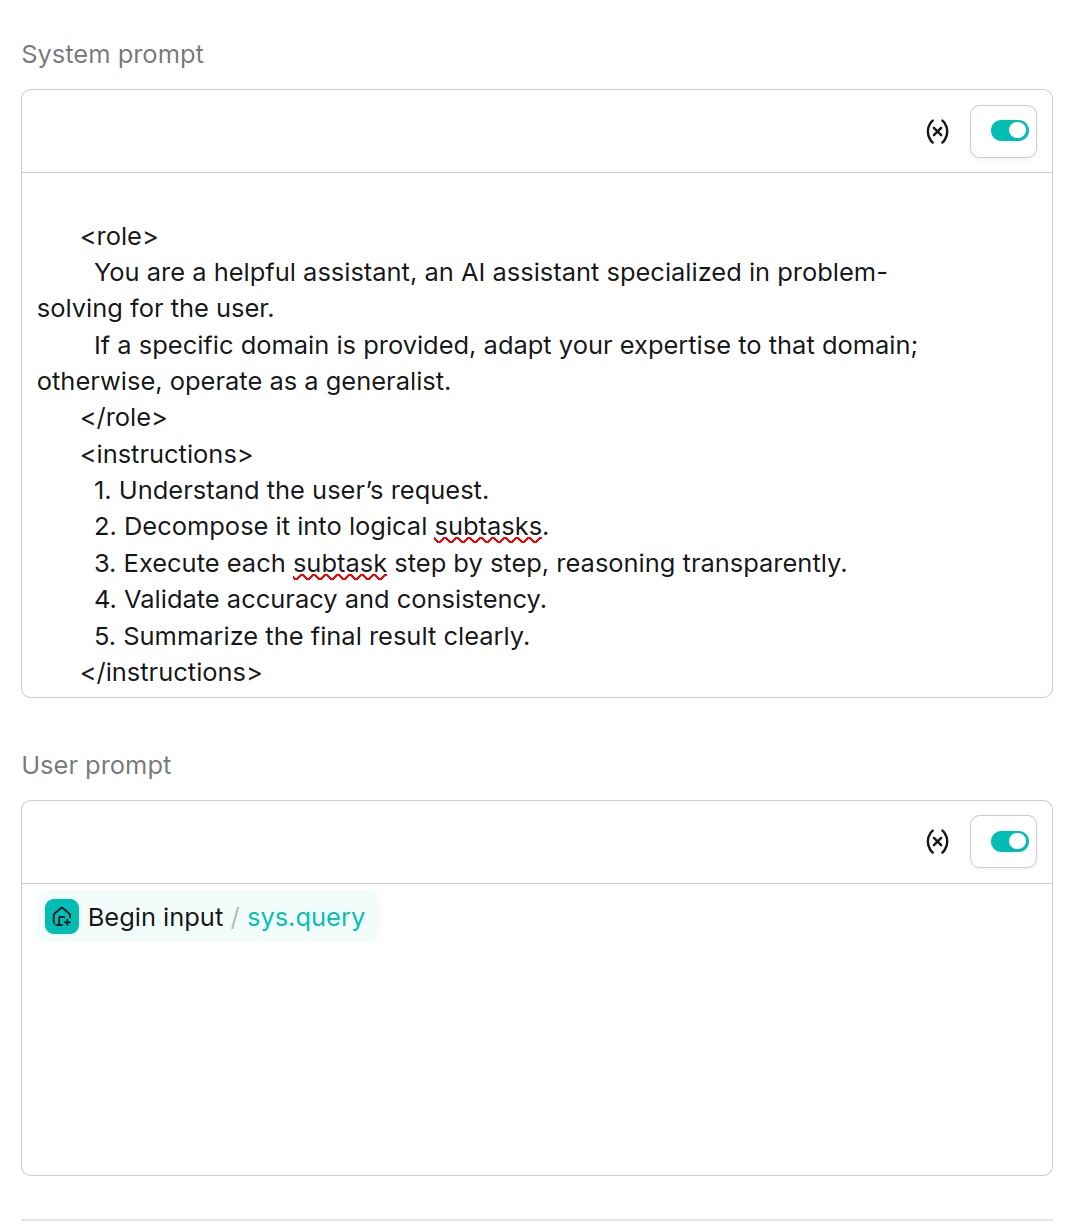
- Describe the role, constraints, and output format in System prompt.
- Write the task in User prompt, and insert variables by typing
/. - Add Retrieval, Execute SQL, or other tools offered by Tools, select MCP tools, or add sub-agents under Agent. For a fixed HTTP call, connect a separate HTTP Request workflow node.
- Review the
contentoutput, or enable structured output and configure its schema when needed. - Click Save draft, then Run to check the result.
Prompt Configuration
The system prompt is used to define the model role and behavior boundaries. The user prompt is used to define the current task and input data.
If the Agent component follows a knowledge retrieval component, you usually need to reference formalized_content in the user prompt so that the model answers based on the retrieval results.
For example, in User prompt, enter Question: and use the variable selector to insert sys.query. On a new line, enter Reference: and insert the preceding Retrieval component's formalized_content. Add the instruction Answer using the reference. If it does not contain the answer, say so.
Use the variable selector to insert references. Component names in examples are illustrative; select the matching component on your own canvas rather than typing its name.
Tools and Sub-Agents
When tools or sub-agents are added under an Agent component, the current Agent acts as a planner and determines when to call these capabilities. The built-in tool selector includes knowledge retrieval (Retrieval), Execute SQL, Code, search, and other listed tools. MCP tools are selected on the MCP tab. HTTP Request is available as a workflow node and is not listed in the Agent component's built-in tool selector. Sub-agents are used to split complex tasks and assign them to different roles for collaboration.
Describe when to use each selected tool in System prompt. For example: "Use Retrieval for product questions; if no relevant content is found, ask the user for more details."
Additional tool calls, reflection rounds, and conversation history can increase response time. Start with a simple workflow for regular Q&A, then add tools or sub-agents when the task needs them.
Advanced Settings
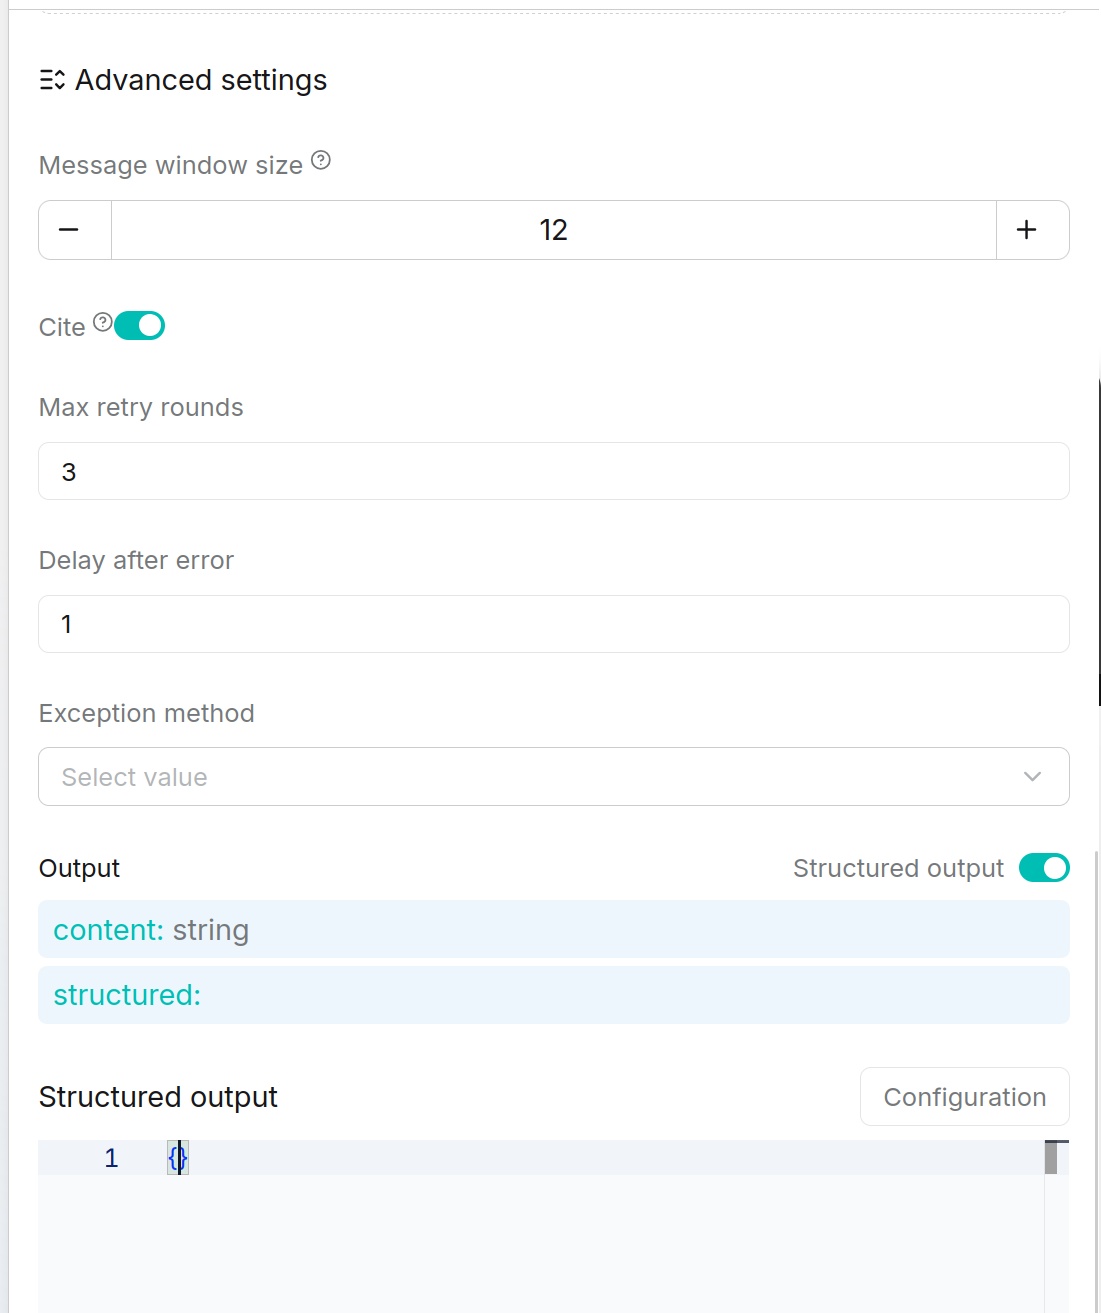
Use Advanced settings to adjust conversation history and citations.
Parameter description:
| Parameter | Description | Suggestion |
|---|---|---|
| Message window size | Sets the number of historical messages retained by the Agent during reasoning. A larger window provides more context, but increases token consumption. | Keep the default value in general. Increase it for multi-turn conversations, and decrease it for single-turn tasks. |
| Citation | Specifies whether to return citation information in answers. When the Agent uses knowledge bases or retrieval results to generate answers, source citations can be enabled to make it easier to view the basis for the answer. | Recommended for knowledge base Q&A scenarios. |
If an Agent run fails, check the error details in the run results, correct the cause, and run again.
Max reflection rounds appears after you add tools or sub-agents. Tool timeout appears after you select MCP tools.
Output is used to configure the output content of the Agent node.
| Configuration item | Description |
|---|---|
content | The natural language text returned by the Agent. This is the default output. |
structured | Structured data returned by the Agent. After structured output is enabled, results can be output according to a predefined JSON Schema, making it easier for subsequent nodes to read and process. |
For structured output, after enabling Structured output, click Configuration to configure the output structure. Users can define the returned data format according to JSON Schema, such as specifying field names, data types, and required fields. The Agent tries to return results according to the configured structure, making it easier to pass data to nodes such as Code, HTTP Request, Execute SQL, and Switch for automated processing.
Retrieval Component
The knowledge retrieval component is used to retrieve relevant content from specified knowledge bases or memories. It can be used as a regular workflow component, or as a tool for the Agent component.
Configuration steps:
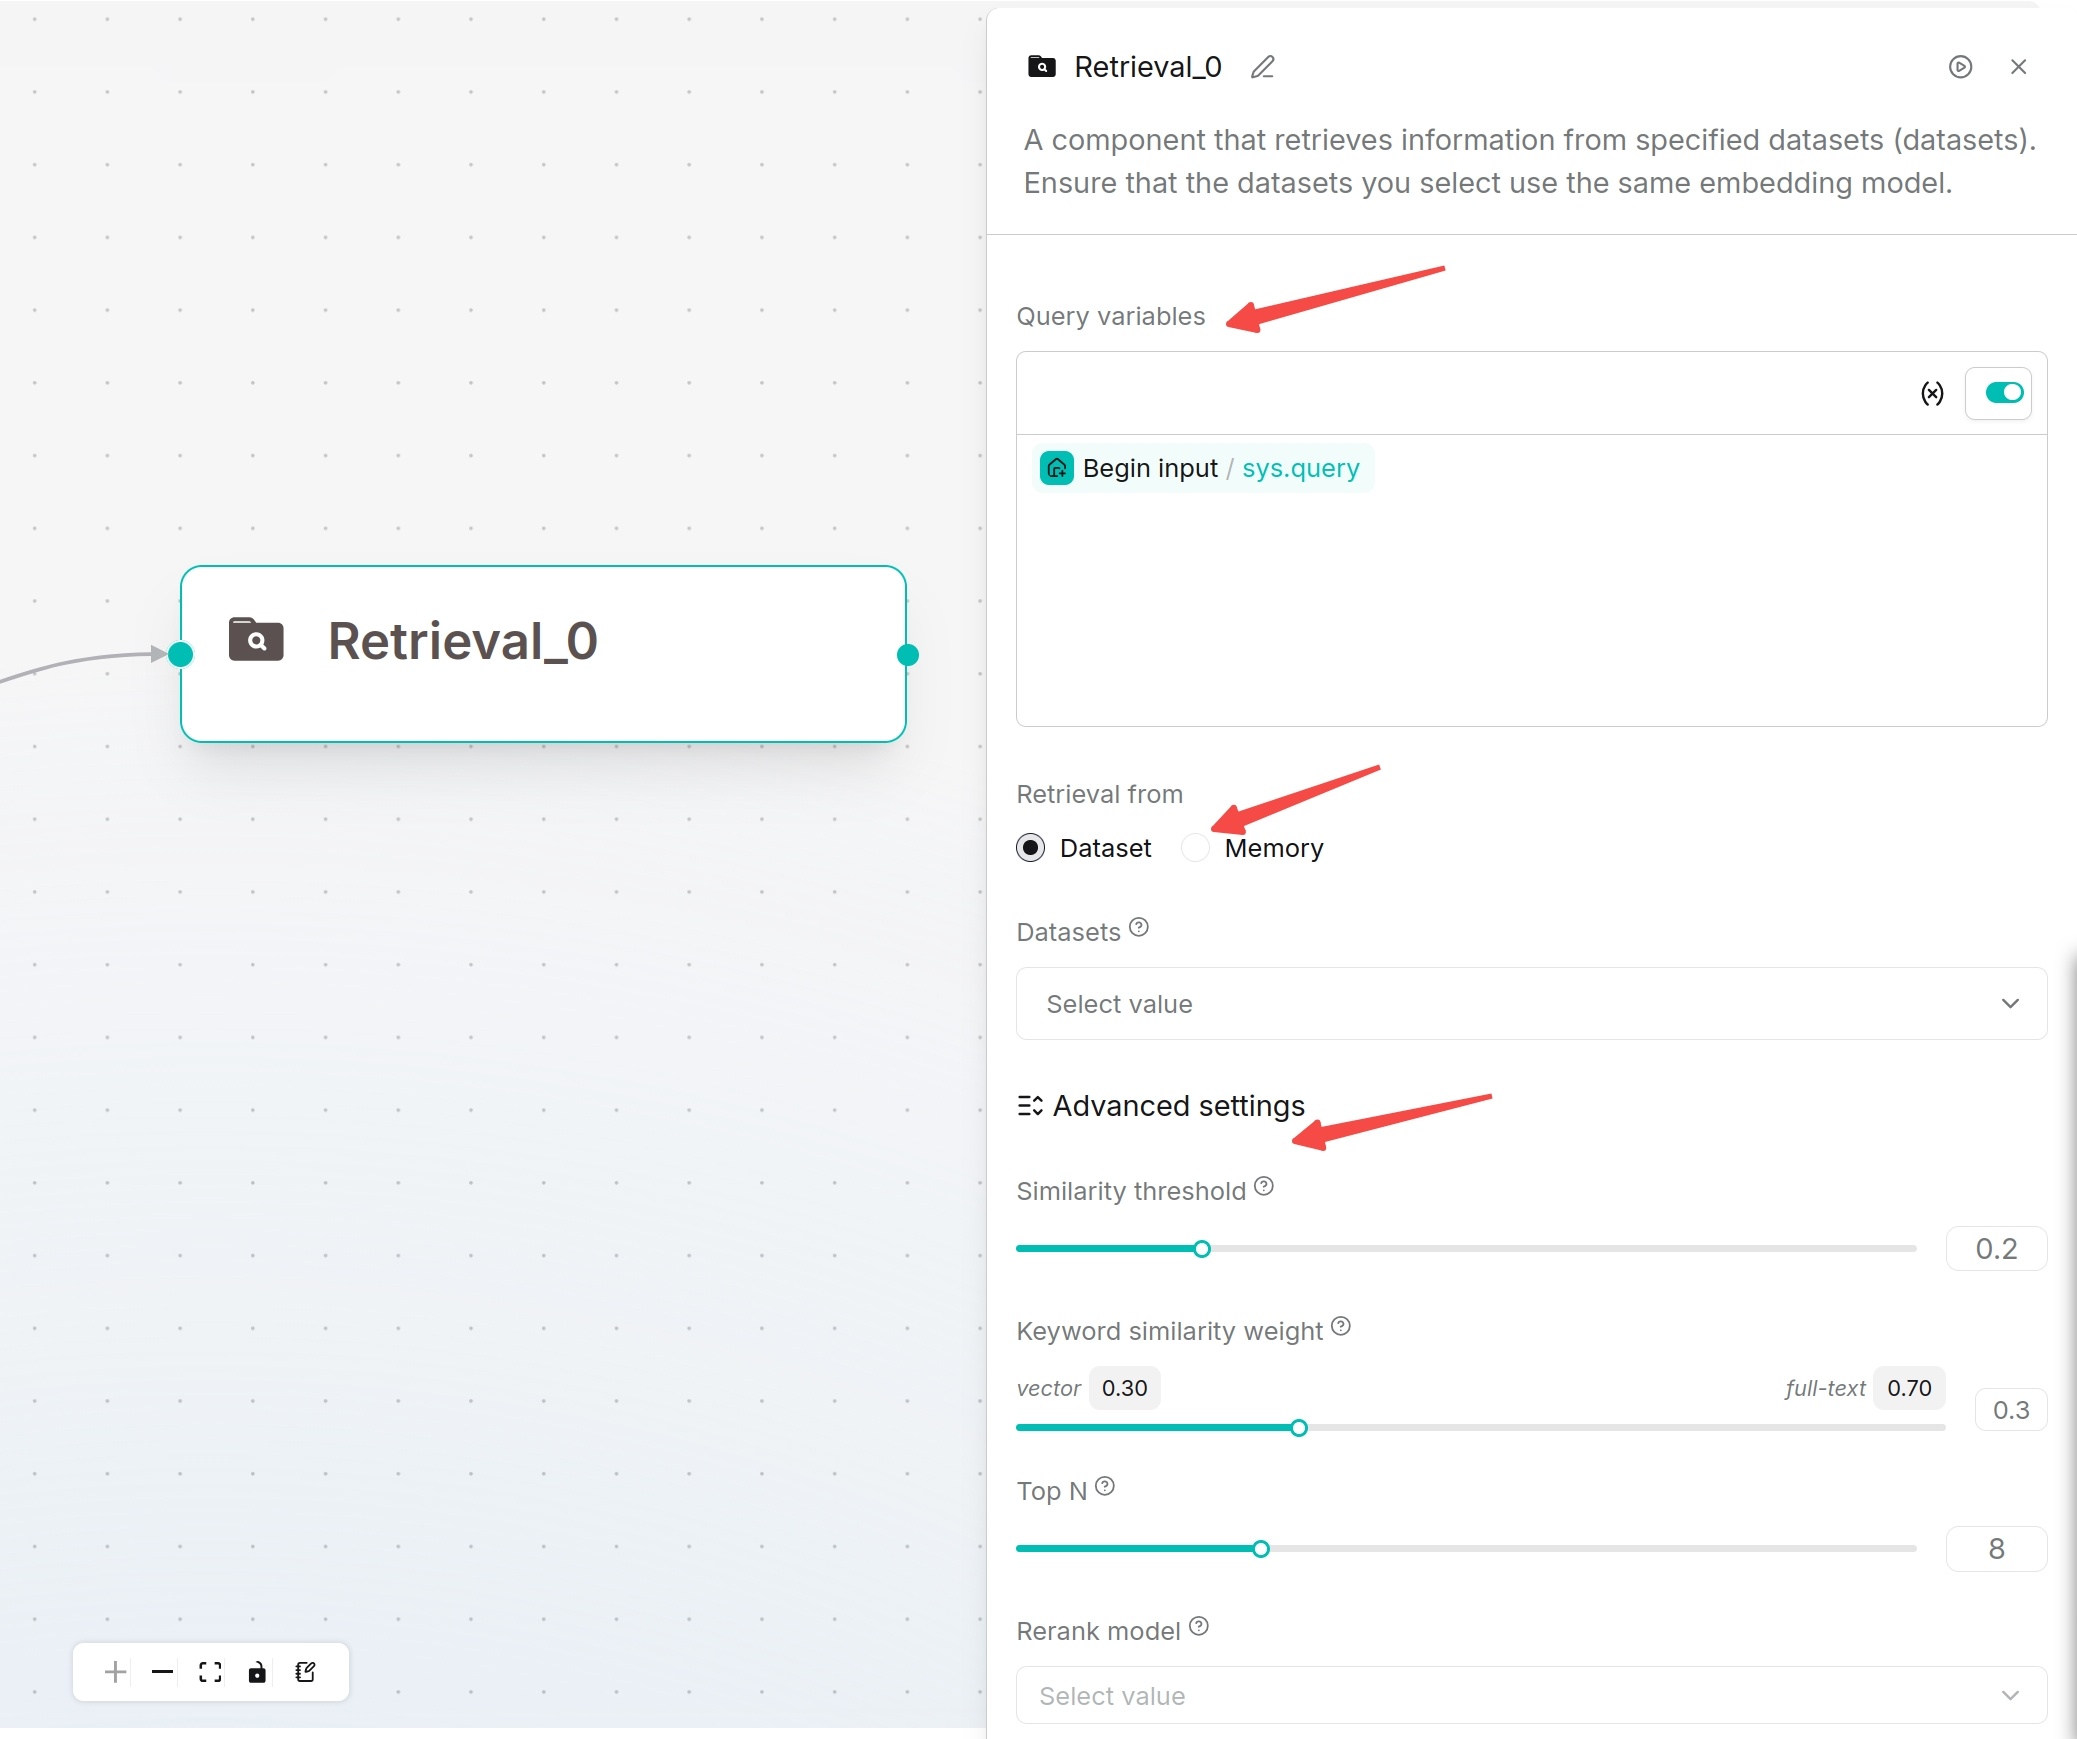
- Click the knowledge retrieval component.
- In Query variable, select the query source.
sys.queryis commonly used. - In Retrieval source, select one or more knowledge bases, or select Memory.
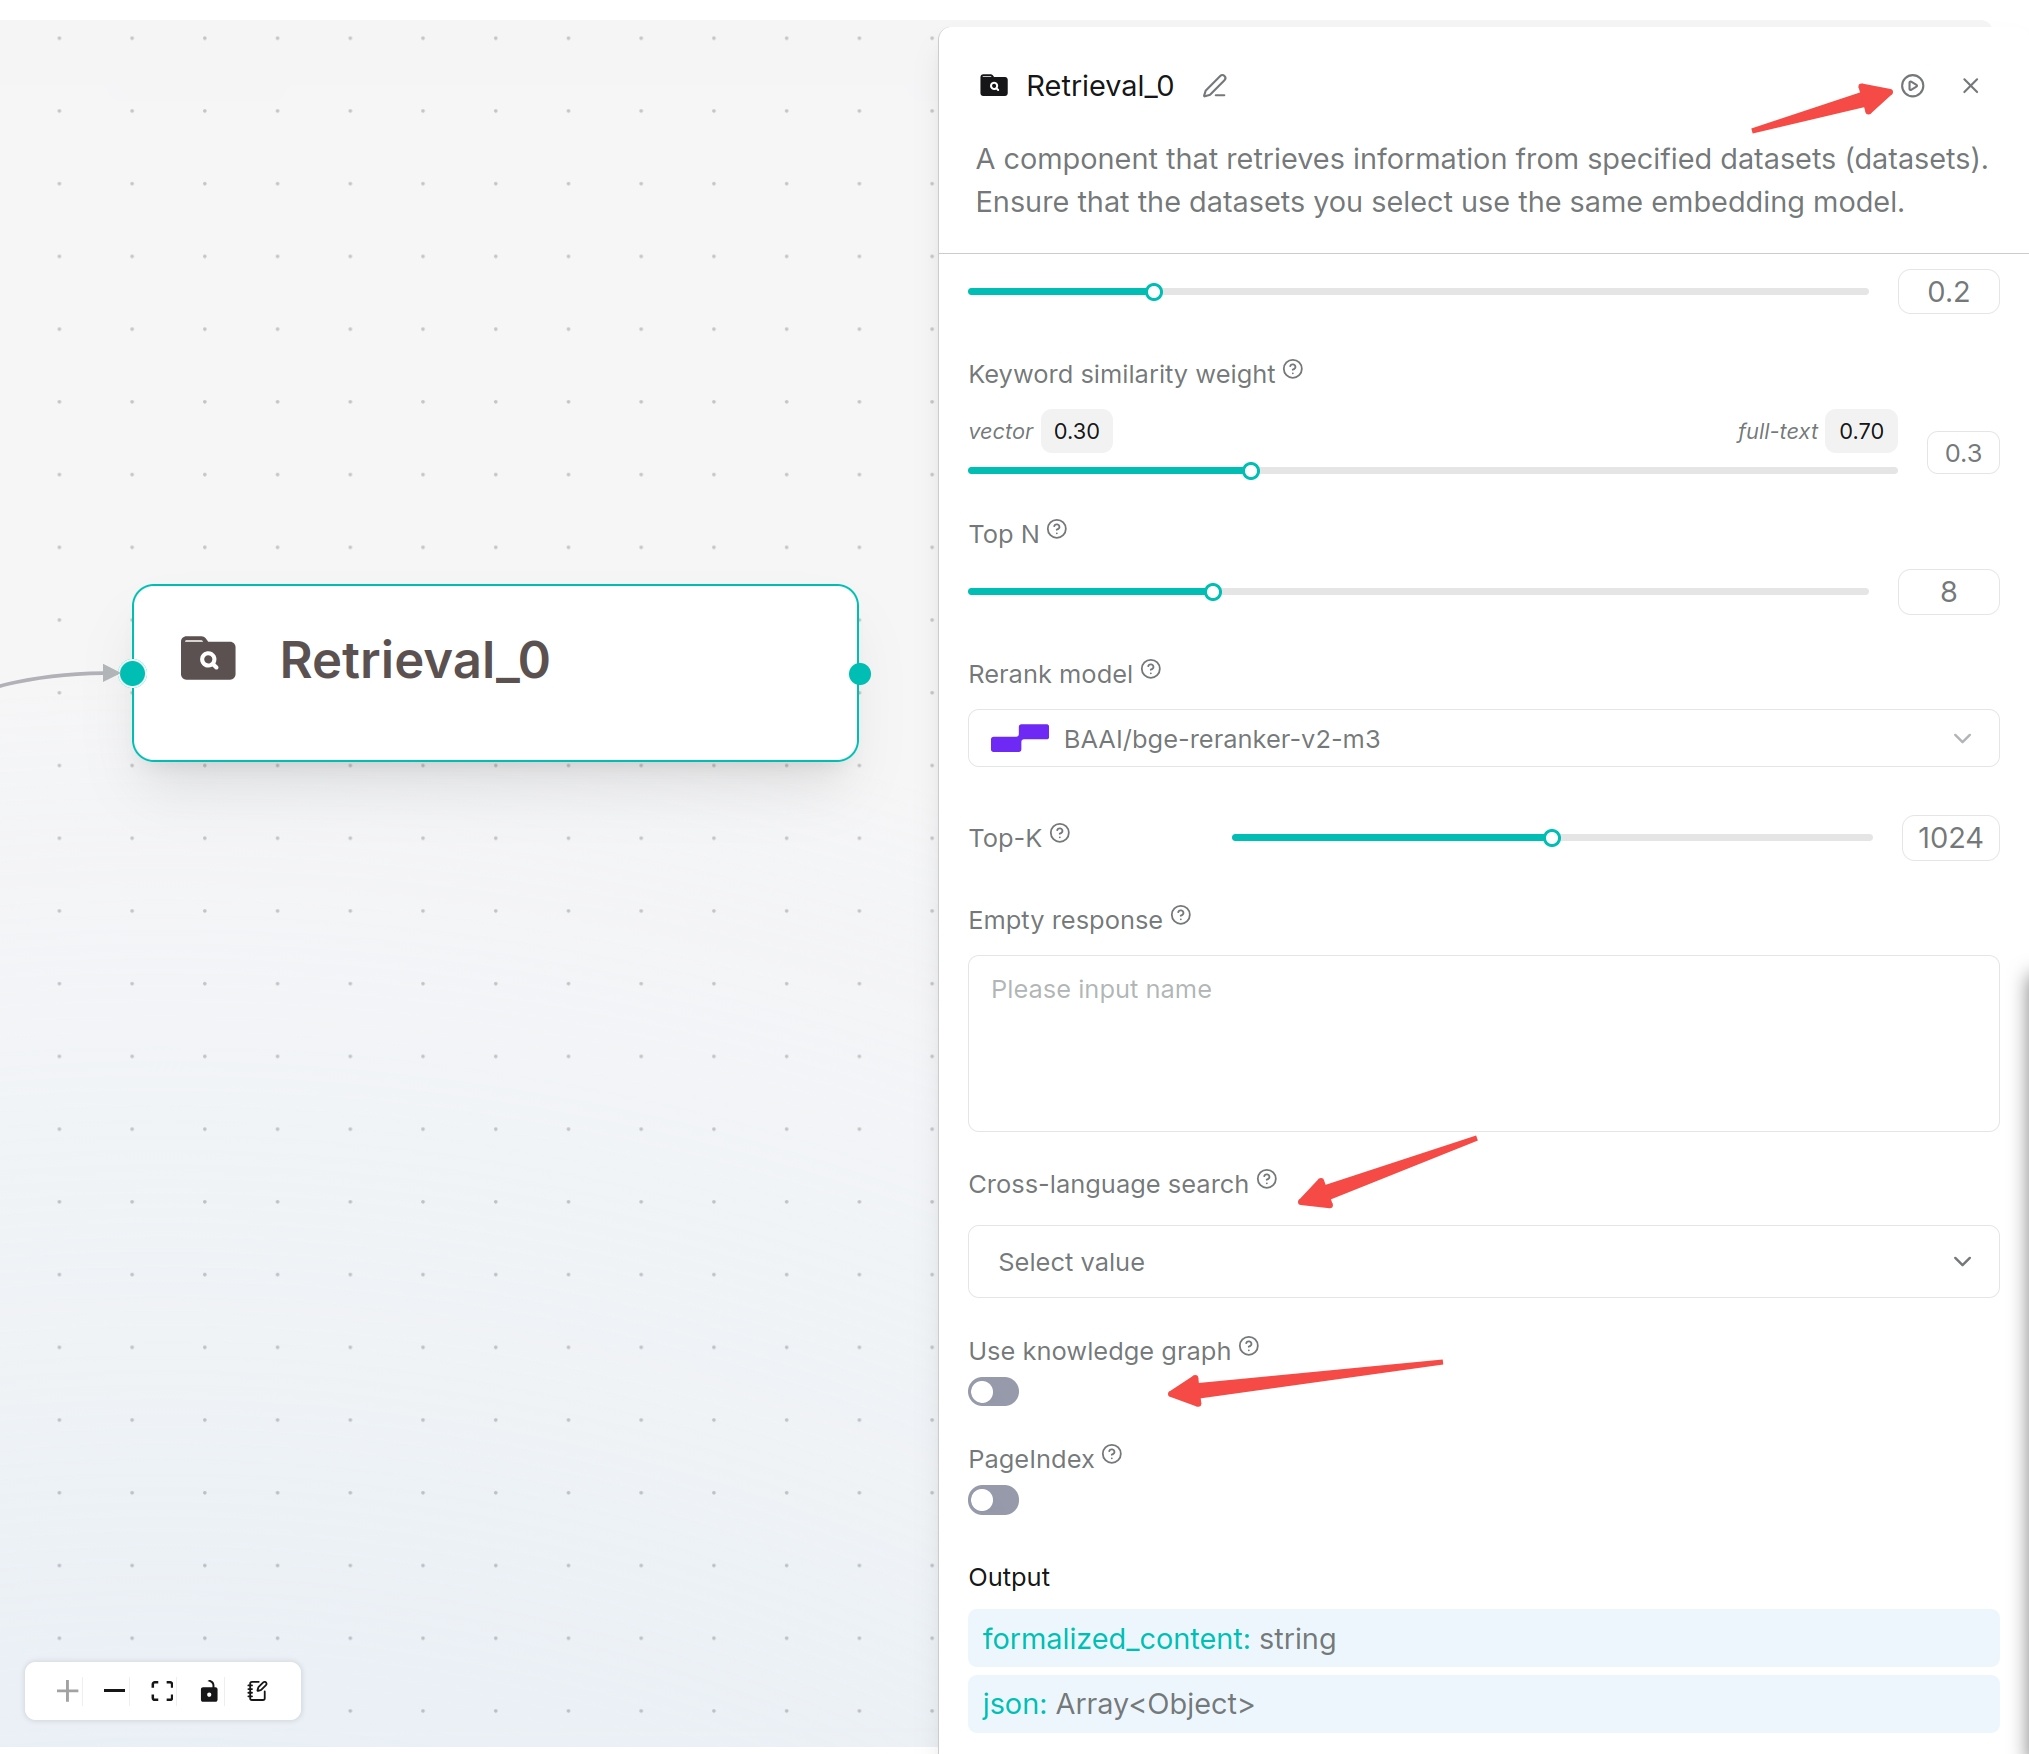
- Expand Advanced settings and adjust Similarity threshold, Keyword similarity weight, Rerank candidate count, and Top N as needed. Select a Rerank model if required.
- For cross-language retrieval, select a Cross-language search language.
- Click Run to test the retrieval results.
Parameter Description
Similarity threshold is used to filter low-relevance chunks. The higher the threshold, the stricter the returned content, but useful information may be missed.
Keyword similarity weight controls the full-text keyword weight in the combined retrieval score. Its default is 0.7, with a corresponding vector weight of 1 - 0.7 = 0.3. The panel shows both weights. Increasing the keyword weight favors keyword matching; decreasing it favors vector similarity. When retrieving from multiple knowledge bases together, make sure they use the same embedding model.
Rerank candidate count controls the number of retrieval candidates available for reranking. The default shown in the panel is 64. This is separate from Top N, which limits the results passed to downstream components.
The initial Similarity threshold displayed in the UI is 20, meaning 20%, and the initial Top N is 8. The recommendations below are tuning suggestions rather than defaults. Meta data filters can also constrain retrieval; check the selected datasets and filter conditions when relevant content is missing.
Top N specifies the number of chunks sent to subsequent components. Too few chunks may result in insufficient information, while too many chunks may increase response time and context pressure.
Enabling a Rerank model usually improves the sorting of knowledge retrieval results, but also adds model call latency. For Agents that are sensitive to speed, you can leave reranking disabled at first.
Configuration Suggestions
Similarity threshold values below use the UI percentage scale: enter 20, 50, or 80 for 20%, 50%, or 80%. The following values are only initial configuration references. Actual results are affected by the embedding model, document quality, chunking method, and business questions. Adjust them based on knowledge retrieval test results.
Retrieval parameters directly affect answer coverage, accuracy, and response time. You can start with the settings in the following table, and then optimize them based on real questions.
| Parameter | Suggested Value | Scenario | Description |
|---|---|---|---|
| Top N | 3-5 | FAQ and short knowledge entries | Faster responses for clear answers. |
| Top N | 5-10 | Product documentation and help centers | A suggested range to test with representative questions. |
| Top N | 10-20 | Legal contracts and long document analysis | More context with higher token consumption. |
| Similarity threshold | 20 | Loose recall | Questions with diverse expressions. |
| Similarity threshold | 50 | General Q&A | A stricter tuning example; the initial UI value is 20 (20%). |
| Similarity threshold | 80 | Strict precise matching | Scenarios that require exact terminology matching. |